TL;DR
- What it is: A propensity model scores the probability that a specific customer will take a specific action, such as defaulting, closing an account, or accepting an offer.
- The core sequence: Frame the decision, assemble features, train candidate models, validate independently, deploy behind a champion and challenger, then monitor.
- Where validation actually fails: Most build guides stop at accuracy. A propensity model also needs calibration, a temporal holdout, and backtesting against real outcomes before it earns a production decision.
- Deployment without losing control: Every score needs a traceable reason and an approval gate before it changes a customer’s treatment, not just a promotion checklist.
- Where it applies: Credit approvals, growth and cross-sell targeting, retention outreach, and collections prioritization all run on the same underlying model type.
- One caveat: This covers the general build-to-deploy sequence. Collections-specific mechanics, including contact strategy and conduct rules, are covered in the dedicated guides linked below rather than repeated here.
A propensity model that ranks customers well on a spreadsheet and then fails the moment it meets production data has usually skipped one of three steps: it was never validated on a genuinely independent holdout, nobody checked whether its probabilities were calibrated, or it shipped without an audit trail. Getting the ranking right is the easy part. Getting a bank to trust the ranking enough to act on it is the actual project.
This is the build, validate, and deploy sequence as it actually runs in a regulated lender, not as a use-case list.
What does a propensity model predict, and what does it not?
A propensity model estimates the probability that a specific customer will take a specific action, such as defaulting, closing an account, or accepting an offer, from that customer’s own behavioral and transaction data. It does not produce a general creditworthiness verdict the way a credit score does; it answers one narrow decision at a time, which is why banks run several in parallel.
That distinction matters more than it sounds. A propensity model tells a bank who is likely to act. A separate decision layer, whether a human policy or an automated rule, decides what treatment that likelihood earns: an approval, an offer, a retention call, a collections contact. Conflating the two is how a bank ends up with a model that scores well and a program that still doesn’t work, because nobody designed the action on the other end of the score.
Different from a credit score. A traditional credit score answers one general question about creditworthiness. A propensity model answers a specific, narrow question tied to one decision: will this customer respond to this offer, leave in the next quarter, or default in the next ninety days. Banks typically run several propensity models in parallel, one per decision, rather than one general-purpose score.
What data and features does a propensity model run on?
A propensity model runs on first-party behavioral data, transaction history, product usage, account activity, and service interactions, plus third-party or bureau data where available to add context. The behavioral features carry most of the signal, since what a customer recently did predicts the next action better than who they are on paper.
Feature engineering is where most of the real work sits. Raw transaction logs are not features. A bank turns them into signals such as recency and frequency of activity, trend direction over the last several months, and changes in behavior relative to that customer’s own baseline rather than the population average. A drop in a normally steady customer’s balance means something different from the same balance in a customer who has always been volatile.
Turing’s Data Accelerator module addresses the tracing problem directly. It ships with 50,000 pre-built features carrying full lineage back to source, so a feature used in a live model can be traced to exactly where its value came from, not reconstructed after the fact.
Data quality decides the ceiling. A model can only be as good as what feeds it. Missing values, stale bureau pulls, and schema drift between the training extract and the production feed are the most common reasons a propensity model that performed well in testing underperforms once it is live.
How do you choose a propensity model and prove it holds up before deployment?
Building a propensity model that survives production means six steps in order: frame the decision the score will drive, assemble and engineer features, train candidate models, validate independently, deploy behind a champion and challenger, then monitor. Jumping straight to accuracy is the common failure; calibration, stability, and explainability decide whether a score is safe to act on.
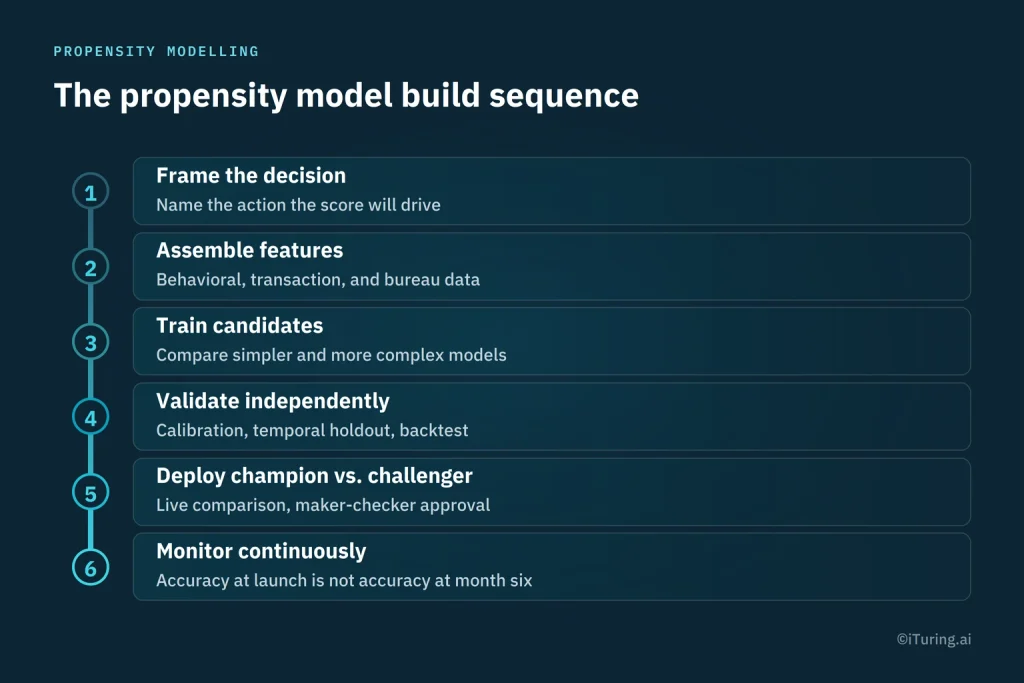
- Frame the decision. Name the exact action the score will drive before building anything. A propensity-to-default score for credit decisioning needs a different time horizon and feature set than a propensity-to-churn score for retention.
- Assemble and engineer features. Pull the behavioral and bureau data, build recency, frequency, and trend features, and check for leakage, where a feature accidentally encodes information from after the event you’re trying to predict.
- Train candidate models. Simpler models such as logistic regression stay competitive for interpretability-heavy decisions like credit. Gradient-boosted models usually win on raw predictive power for less regulated decisions like a marketing offer, at the cost of needing more explainability work later.
- Validate independently, covered in the next section, because this is the step most build guides skip past.
- Deploy behind a champion and challenger, covered further down.
- Monitor continuously once live, since a model’s accuracy at launch says nothing about its accuracy six months later.
The step most general guides underdescribe is validation, and it’s the one that decides whether a bank can trust the score enough to act on it.
What does independent review check before a propensity model goes live?
Independent review checks four things beyond raw accuracy: whether the reviewer is genuinely separate from the build team, whether the model’s probabilities are calibrated to real outcomes, whether performance holds across segments and over time, and whether each score carries the factors that drove it. RBI’s draft guidance expects that separation of duties explicitly.
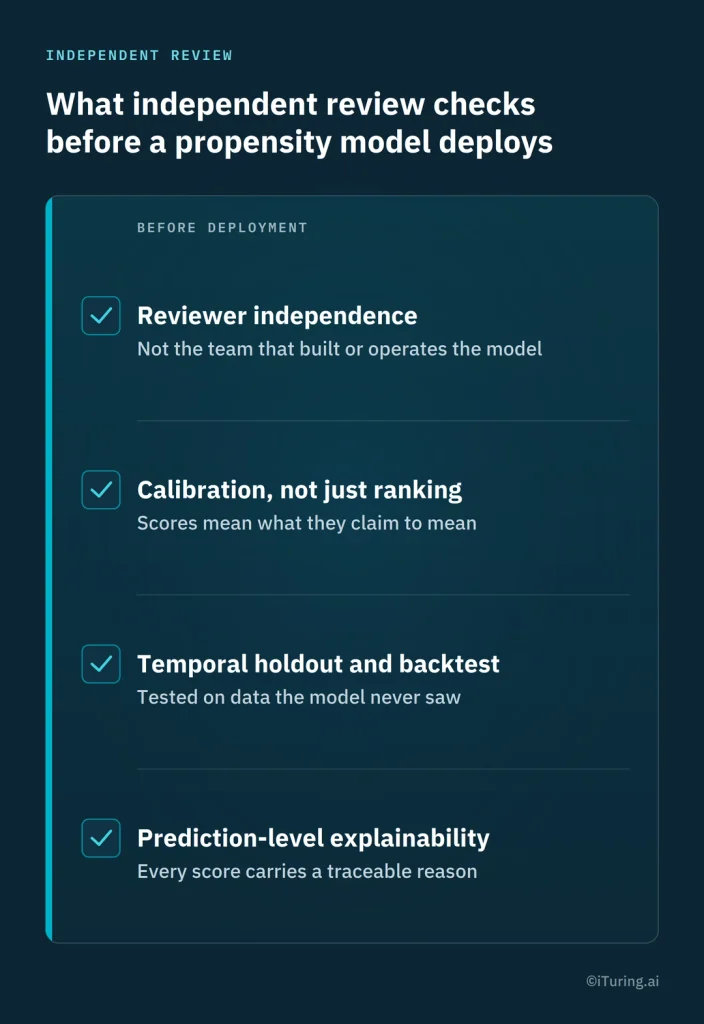
Calibration is a separate question from accuracy. A model can rank customers correctly, putting the riskiest ones at the top, while still being badly calibrated, meaning a customer scored at 80% probability doesn’t actually default 80% of the time. A bank acting on the raw score for a business decision, such as setting a credit limit, needs the number itself to mean something on its own terms.
The holdout has to respect time. A random train-test split lets a model see patterns from the future leak into its training data, which is a common way propensity models look strong in testing and then disappoint in production. A holdout period that comes strictly after the training window, matching how the model will actually be used, is what a genuine validation review checks for.
Explainability travels with the score, not behind it. A propensity score without a reason attached is a number a business team has to trust blind. iTuring builds explainability at the individual prediction level into the platform itself, so every score a propensity model produces carries the specific factors that drove it, reviewable by a validator or an examiner without reconstruction after the fact.
How do you deploy a propensity model without losing the audit trail?
Deployment is where accountability shows up, because a score starts changing what happens to a real customer. Roll out behind a champion and challenger rather than a single cutover, log every score with the inputs and model version behind it, and keep the reasons attached to each decision, so an examiner’s question has an answer on record.
Champion and challenger, not a single cutover. A new propensity model runs alongside the current production model on live traffic before fully replacing it, so its real-world performance is measured against the model it’s meant to replace rather than assumed from offline testing alone.
Every promotion goes through an approval gate. Moving a challenger model into the champion position is a decision with a name attached, not an automatic swap once a metric crosses a threshold. A maker-checker approval step, where the person promoting a model is not the same person approving the promotion, keeps that decision accountable.
The audit trail has to be immutable and complete. From the data a model trained on, through every version it went through, to the specific explanation behind every score it produced in production, that full lineage needs to sit somewhere a validator or examiner can pull it on demand rather than have it reconstructed from scattered logs after the fact. iTuring’s Model Risk Management and ML Ops modules are built around exactly that continuous record, so deployment doesn’t create a gap between what the model does and what the bank can prove it did.
Where does a propensity score change a decision, beyond collections?
A propensity score reshapes several decisions. In credit decisioning, a propensity-to-default score lets a bank approve more borrowers at the same risk appetite instead of tightening the whole book. It also drives churn retention, next-best-offer targeting, and deposit growth, each scoring a different action from the same behavioral foundation.
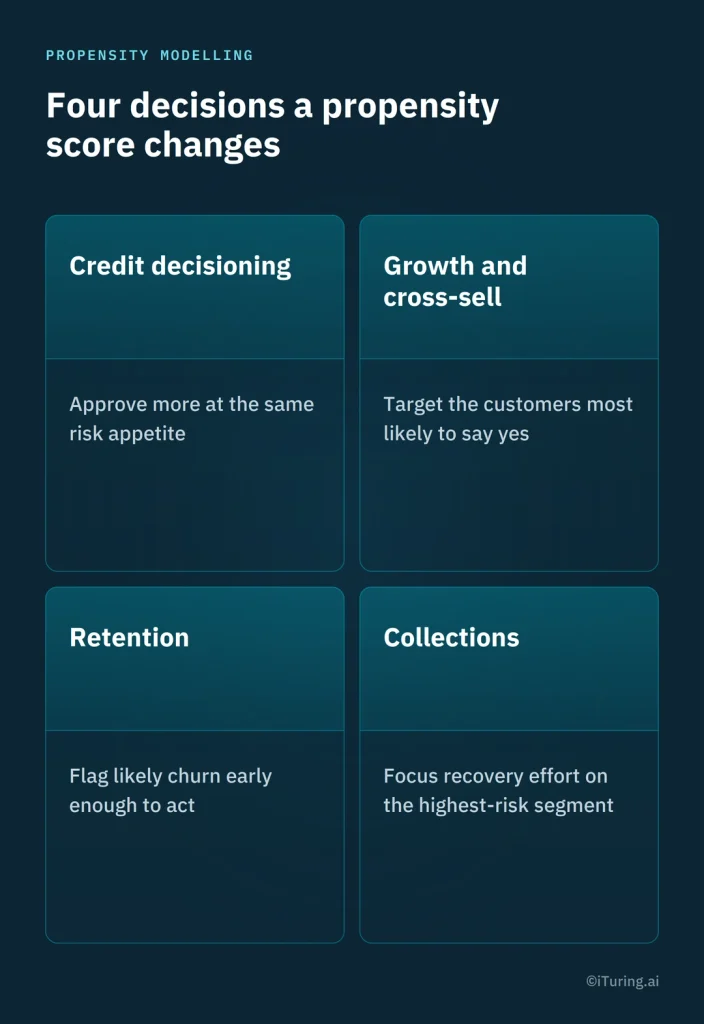
Credit decisioning. A propensity-to-default score feeds underwriting, letting a bank approve more borrowers at the same risk appetite instead of tightening the whole book to manage a subset of risky accounts.
Growth and cross-sell. A propensity-to-accept score for a specific product targets the customers most likely to say yes to a new account or a credit line increase, instead of running the same offer at everyone.
Retention. A propensity-to-churn score flags accounts likely to close or go dormant early enough that an intervention still has time to work, rather than after the customer has already stopped using the account.
Collections is the same model type applied to recovery. A leading NBFC in India used a propensity-to-default model to rank borrowers by risk and focus collections effort on the highest-risk segment, capturing 72% of likely defaulters by targeting only the top 30% highest-risk customers, and saw a 116% improvement in collections and 86% predictive accuracy, deployed in two weeks. Collections has its own contact-strategy and conduct requirements that deserve their own treatment. For that depth, see the dedicated guides for propensity modeling in NBFC collections and propensity models for US bank collections.
If your team is scoping a propensity model and wants the validation and audit-trail work built in rather than bolted on afterward, book a working session with our data science team.
Sources
- iTuring case study, “Improve Collections and Optimize Efforts” (Leading NBFC in India): 116% collections improvement, 86% predictive accuracy, two-week deployment, 72% of likely defaulters captured targeting the top 30% highest-risk segment. https://ituring.ai/case-study/improve-collections-and-optimize-efforts/
- iTuring, Data Accelerator platform page (25,000+ pre-built financial features, full lineage). https://ituring.ai/platforms/open-data-accelerator/
- iTuring, Model Risk Management platform page (explainability, audit trail, maker-checker approval). https://ituring.ai/platforms/model-risk-management/